Most agent benchmarks are not wrong on purpose. They are contaminated: the task set leaked into training, the fixtures moved between runs, the judge graded the producer's own claims, the good-looking samples got kept. The number comes out high and means nothing. Here are the six places a benchmark lies to you, the disciplines that each one needs, and a diagram and a worked example of a benchmark cheap enough to run and honest enough to act on.
Read More
Most API authorization bugs get described as a missing check, as if someone forgot an if statement. They are almost never that. They are a missing state model: the system never defined, as data it enforces, who owns this object, what tenant it belongs to, what this role may do, or what this token is scoped for. Where that state is undefined, the server falls back to trusting the request, and trusting the request is the bug. Here is the frame, the five places it shows up, and why testing endpoint by endpoint will never find it.
Read More
Use-after-free gets filed under 'C is dangerous', which is the wrong lesson and hides the real one. The bug is not the free. It is a reference that outlived the thing it pointed to, and nothing enforced that the two lifetimes had to match. That failure shows up in any language that lets a pointer outlive its referent without the type system stopping it. C is just the one honest enough not to hide it from you. Here is the actual mechanism, a reproducible control-flow hijack on your own machine, and why the fix is lifetime ownership, not avoiding a language.
Read More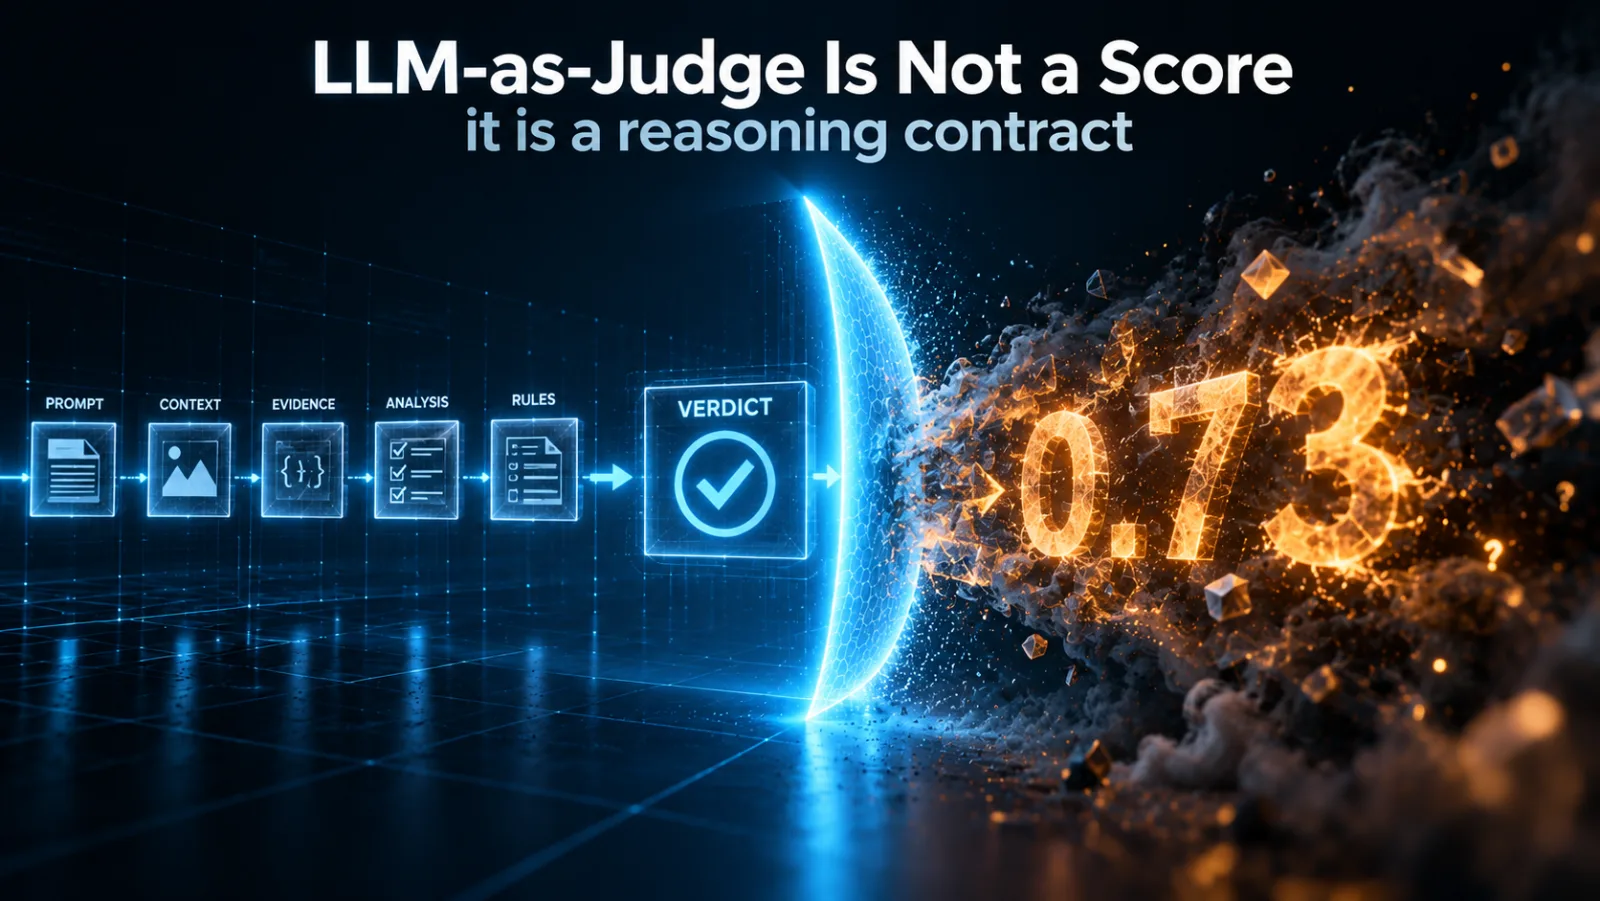
Most teams use an LLM judge as a scorer: prompt it, read the number, gate on it. That is the mistake. A scorer returns a number you cannot audit and cannot trust. A judge is a contract with four clauses: the evidence it is allowed to use, the rubric that binds its reasoning, the schema it must answer in, and the external check that can veto it. Get those four right and the number means something. Skip them and you have automated a vibe.
Read More
A webhook is not an HTTP request. It is an untrusted, replayable, out-of-order, at-least-once message stream that happens to arrive over POST, and it has a public address. Most webhook bugs are not injection. They are the distributed-systems failures you already know (replay, duplicate delivery, reordering, retry storms) showing up at an endpoint nobody treated like a message consumer. Here is the trust boundary, the five failures, and the actual checks, at a depth you can run against your own endpoint.
Read More
Jev is a decision model that returns a calibrated confidence with every answer. I ran 1,200 agent tool-call decisions through it for about five cents to see whether that confidence is worth routing on. It held up against adversarial traps better than I expected. But the confidence scalar the API returns is worse calibrated than the raw class probabilities it ships in the same response, and the place it breaks is not the hard cases. It is the ambiguous ones.
Read More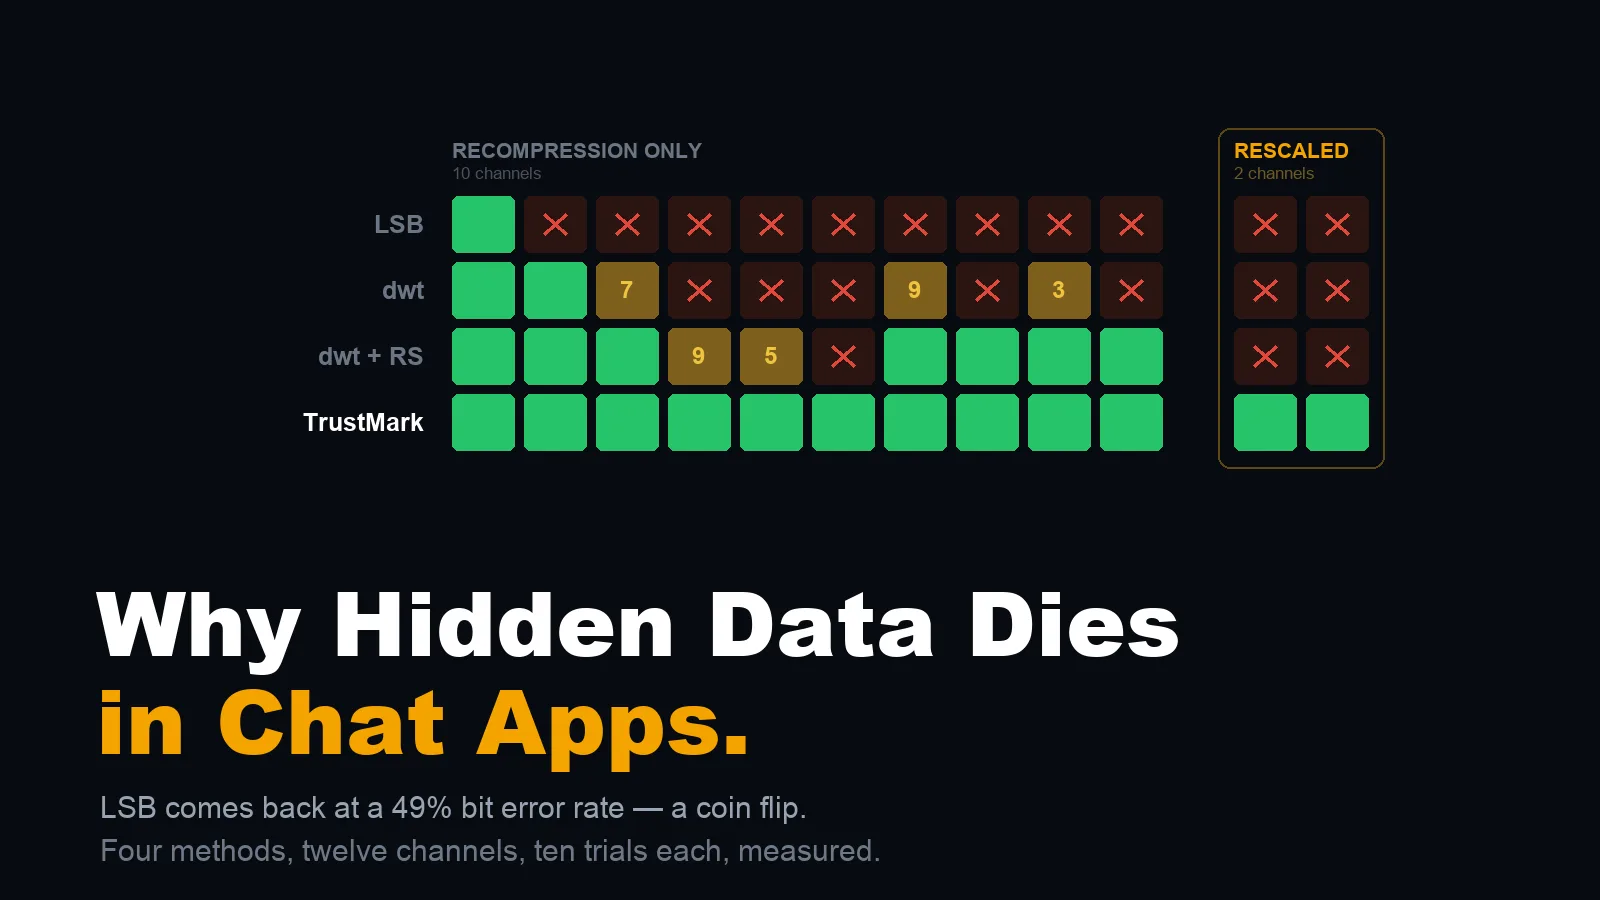
Every 'hide a message in a photo' tutorial uses LSB. Push it through a simulated WhatsApp send and the bit error rate is 49%, which is a coin flip: not degraded, gone. Four methods measured across twelve channels — why Reed-Solomon takes WhatsApp from 0/10 to 10/10, why resize defeats every classic method, and why the learned watermark that clears it is also the least visible.
Read More
One harness treats MCP as core infrastructure and spends tens of thousands of lines on it. The other refuses it on principle and tells the agent to write its own tools instead. Both positions are coherent, and the disagreement is not about capability. It is about who owns the schema, what a stable boundary is worth, and what you pay for it in tokens and attack surface on every single request.
Read More
Codex made Item a wire type and thread/fork a protocol call. Pi gave every session entry a parentId. Claude Code compresses the transcript in five stages. Three harnesses, three answers to what the durable unit of agent state actually is, and the answer decides whether running out of context costs you a summary or costs you the work.
Read More
Pi is famous for a system prompt under a thousand tokens. I measured it: 550. Then I measured the four tool schemas that ship beside it in every single request: 588. The celebrated number is the smaller half. Meanwhile Codex ships a different prompt length for every model, from 1,436 to 5,070 tokens, and the reason why is the most useful thing in either codebase.
Read More