Benchmarking an Agent Without Lying to Yourself
Most agent benchmarks are not wrong on purpose. They are contaminated: the task set leaked into training, the fixtures moved between runs, the judge graded the producer's own claims, the good-looking samples got kept. The number comes out high and means nothing. Here are the six places a benchmark lies to you, the disciplines that each one needs, and a diagram and a worked example of a benchmark cheap enough to run and honest enough to act on.
Table of Contents
Most agent benchmarks are not dishonest on purpose. Nobody sits down to fake a number. They just run a benchmark that was contaminated before they touched it, read the high score it produces, and believe it. The lie is structural, and it is comfortable, because the number is the one you were hoping for.
An agent benchmark lies to you in a small number of specific ways. Each one has a discipline that catches it. None of the disciplines cost money; they cost the willingness to run a test that might tell you something you do not want to hear. Here they are, with a diagram of where the contamination enters and a worked example of a benchmark cheap enough to run on a lunch break and honest enough to act on.
The six lies, and what catches each
| The lie | How it sneaks in | The discipline that catches it |
|---|---|---|
| The model saw the test | Tasks scraped from the internet were in training data | Deterministic or held-out task set, never public, never logged |
| The test moved | Fixtures or prompts changed between runs, so scores are not comparable | Fixed, versioned task set; pin everything |
| The judge graded the claim | The scorer read the agent’s own report instead of the result | A judge that reasons over verified facts, with a rule as lie detector |
| Everything looks like a pass | No input that should fail was included | Negative controls and a noise floor |
| The easy cases carried it | Clear tasks inflate the average; the hard ones are where you fail | Split by difficulty: clear, adversarial, ambiguous |
| You cannot run it again | No seed, no saved responses, no trace | Reproducibility: fixed seed, saved raw output, captured traces |
The rest of this is those six, in the order they do the most damage.
Contamination: the test was in the training data
This is the big one and it is invisible. If the tasks you score on were anywhere the model could have read them, the score is inflated by memory, and you cannot tell by how much. A model that has seen the answer key looks brilliant.
The only real defense is a task set the model cannot have seen. Generate it from rules with a fixed seed, so it is provably synthetic and reproducible. Or hold out a private set that never touches the public internet and never gets pasted into a prompt that some provider logs and trains on later. The moment your eval tasks are public, they have a shelf life, and after that they measure recall.
The test moved, so the scores do not compare
If the task set, the prompts, the fixtures, or the model version drift between runs, two scores are not measuring the same thing, and “we went from 61 to 68” is a sentence about nothing. Pin all of it. The task set is versioned. The prompt is versioned. The model id is recorded, not “the latest”. A benchmark you cannot freeze is a benchmark you cannot compare, and comparison is the entire point.
The judge graded the claim, not the result
If a model or a judge scores the output by reading the producer’s own description of what it did, it can pass a run that did the wrong thing perfectly. The scorer has to look at the artifact, reason over facts that were verified independently, and get vetoed when its load-bearing evidence is false. That is a whole topic of its own, which is why an LLM judge is a contract, not a score, and benchmarking inherits every one of its failure modes.
Everything passed, because nothing was supposed to fail
Here is the discipline almost nobody has, and the one that catches the most broken metrics: a negative control.
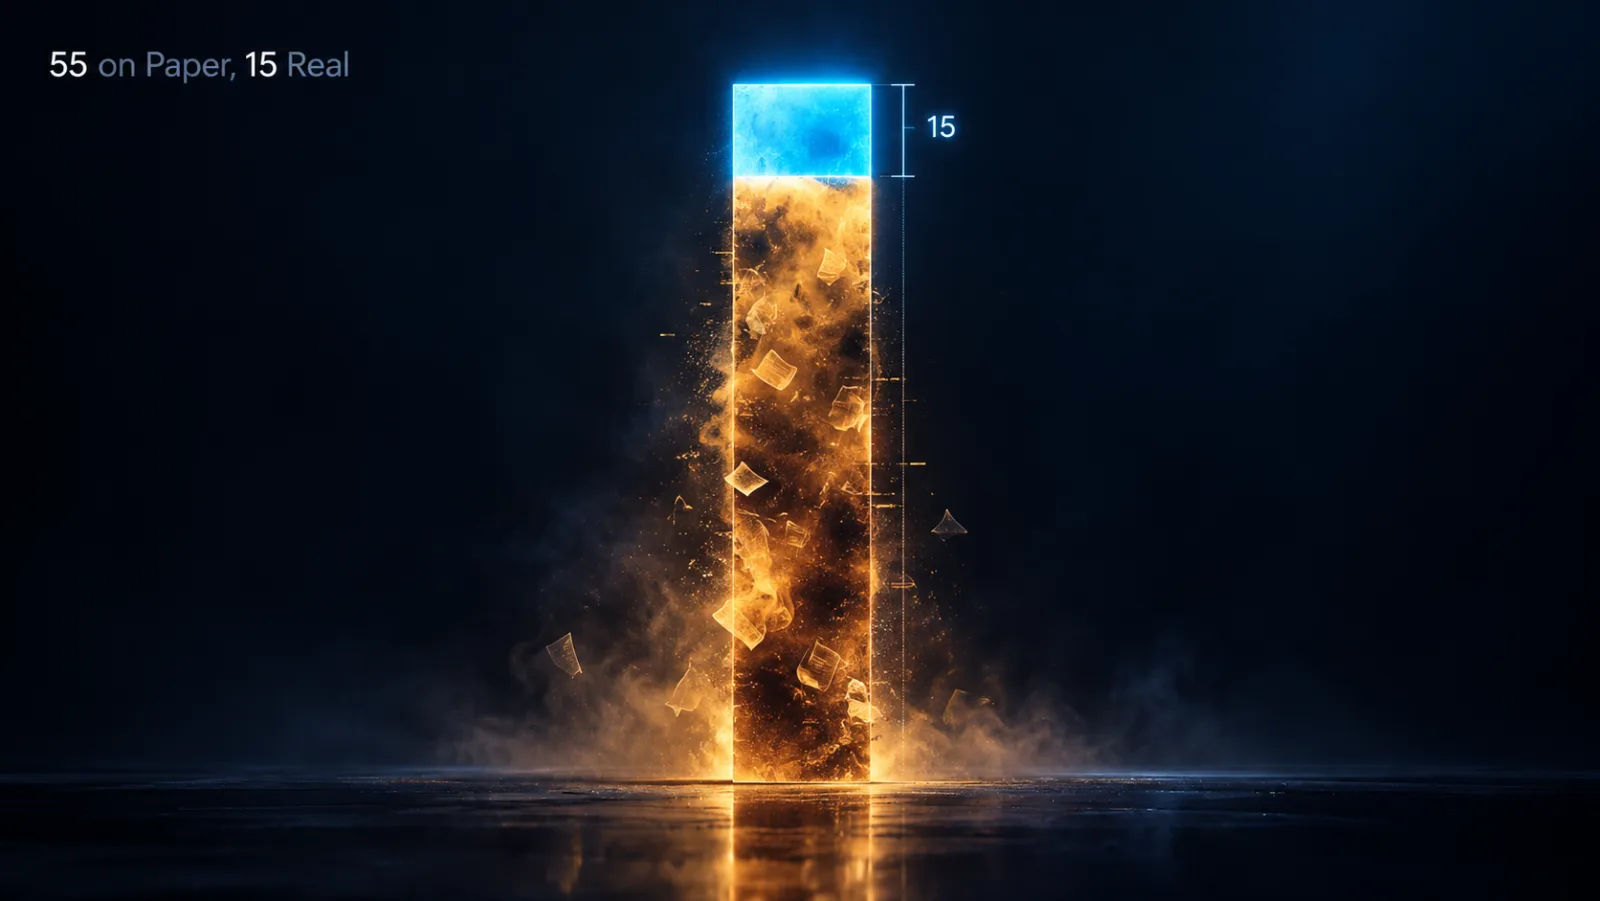
Put inputs in the test that the system should fail, or score low on, on purpose. If your metric passes them, the metric is broken, not the system. The statistical version is a noise floor: run a trivial or random baseline on the same test and see what it scores. If a baseline that does nothing clever gets 40, then your agent’s 55 is 15 points of signal, not 55.
# the question is never "what did my agent score"
# it is "what did my agent score ABOVE a baseline that cannot be doing the task"
signal = agent_score - baseline_score     # baseline = random / trivial / do-nothing
# if signal is small, your benchmark is measuring something every system gets for free
A benchmark without a negative control cannot tell you whether the number is capability or gravity.
The easy cases carried the average
A single averaged score hides its own composition. Clear tasks are easy, there are usually a lot of them, and they drag the mean up while the cases you actually care about fail quietly underneath. Split the set by why a case is hard: clear, adversarial, ambiguous. Report each. The clear number tells you nothing you did not know; the adversarial and ambiguous numbers are the review. A model can post a great average and be useless exactly where it matters, and you will never see it in the mean.
You cannot run it again
If there is no fixed seed, no saved raw output, and no captured trace, you did not run a benchmark, you had an experience. Reproducibility is not a nicety. Save the seed, save every raw response, capture the full trace of what the agent did and not just its final answer, because the trace is where you see it skip a validation, retry three times, or take an action it should not have. A number you cannot reproduce is a number you cannot defend, and one you cannot debug.
What the honest version looks like
Put the disciplines together and the shape is simple.
flowchart TB
  gen["fixed, versioned task set
generated or held out, never public"]
  neg["negative controls
inputs that should fail, plus a baseline floor"]
  run["run the agent
fixed seed, capture the full trace"]
  judge["score over verified facts
rule vetoes a false-evidence score"]
  split["split by difficulty
clear / adversarial / ambiguous"]
  report["report signal above baseline
with cost and latency, reproducible"]
  gen --> run
  neg --> run
  run --> judge --> split --> report
None of this is theoretical. A calibration test I ran recently came to about five cents for 1,200 decisions: a deterministic task set the model could not have seen, a resampled noise floor as the negative control, scores split by difficulty, and every raw response saved so anyone can re-run it. The full writeup is in the Jev calibration piece, and the point here is that the honesty was in the method, not the budget. It cost discipline, not money.
The one sentence to take
A benchmark number is a claim, and most agent benchmarks are claims you have not earned the right to make. Before you trust one, ask the six questions: could the model have seen this, is the test frozen, did the judge check the result or the claim, what should have failed, which cases actually carried the score, and can you run it again. Where the answers are good, the number means something. Where they are not, you have measured the harness and called it the model, and shipped a story told with numbers.
🎧 More Ways to Consume This Content
I occasionally advise small teams on backend reliability, Go performance, and production AI systems. Learn more: /services
Comments
This space is waiting for your voice.
Comments will be supported shortly. Stay connected for updates!
This section will display user comments from various platforms like X, Reddit, YouTube, and more. Comments will be curated for quality and relevance.
Have questions? Reach out through:
Want to see your comment featured? Mention us on X or tag us on Reddit.