[ HOME ]
[ BLOG ]
[ SERVICES ]
[ PROJECTS ]
[ VIDEOS ]
Benchmarking an Agent Without Lying to Yourself
October 15, 2026
agent-evaluation
llm-benchmark
benchmarking
regression-testing
negative-controls
reproducibility
ai-evaluation
agent-reliability
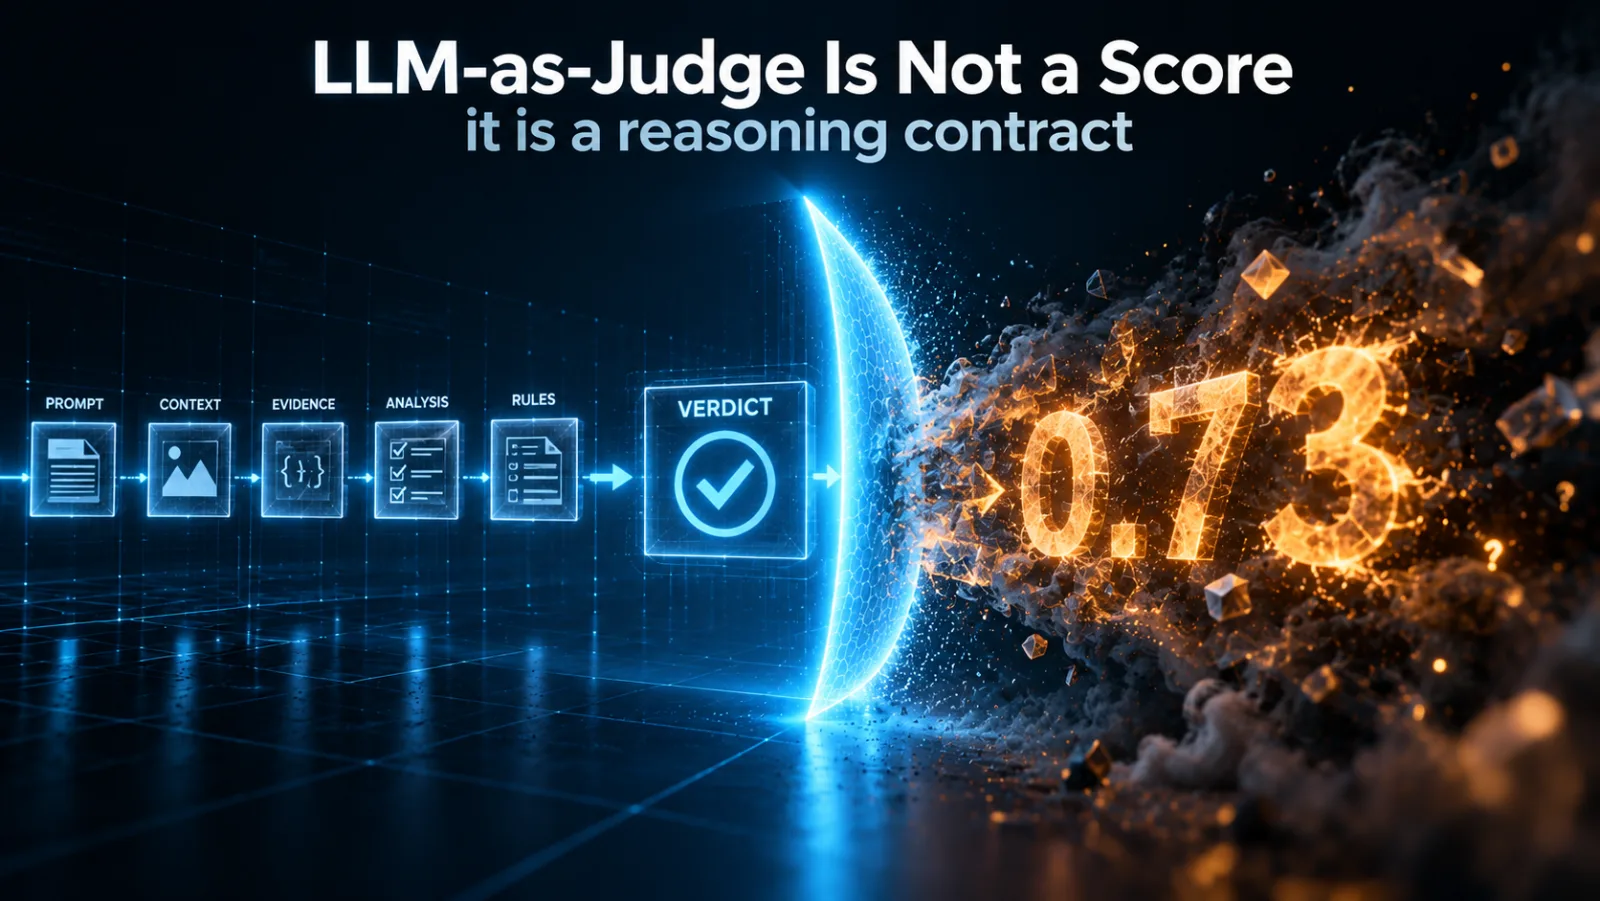
LLM-as-Judge Is Not a Score. It Is a Reasoning Contract.
October 6, 2026
llm-as-judge
llm-evaluation
ai-evaluation
rubric
calibration
judge-drift
agent-reliability
evaluation-architecture
Jev Ships Two Confidence Numbers. The API Hands You the Worse One.
September 28, 2026
jev
typesafe
llm-evaluation
calibration
agent-reliability
llm-as-judge
decision-models
ai-security
[ Connect_With_Me ]
© 2026 HarrisonSec. All rights reserved.