Long-form writing on runtime, distributed systems, kernel internals, Go concurrency, memory models, eBPF, and assembly walkthroughs.
Blog
In a single day of debugging, four different signals each looked like proof and each supported a smaller claim than I borrowed it for. A log line that printed exactly as designed while the process it was in died ten seconds later. An address that looked like proof of a cellular test and was identical on Wi-Fi. A fix that was clean and plausible and would have broken a whole class of users. A ten-minute hang with no error output at all. Evidence is not the problem. Using a true signal to support a claim it cannot carry is.
2026-08-19
9 min read
Blog
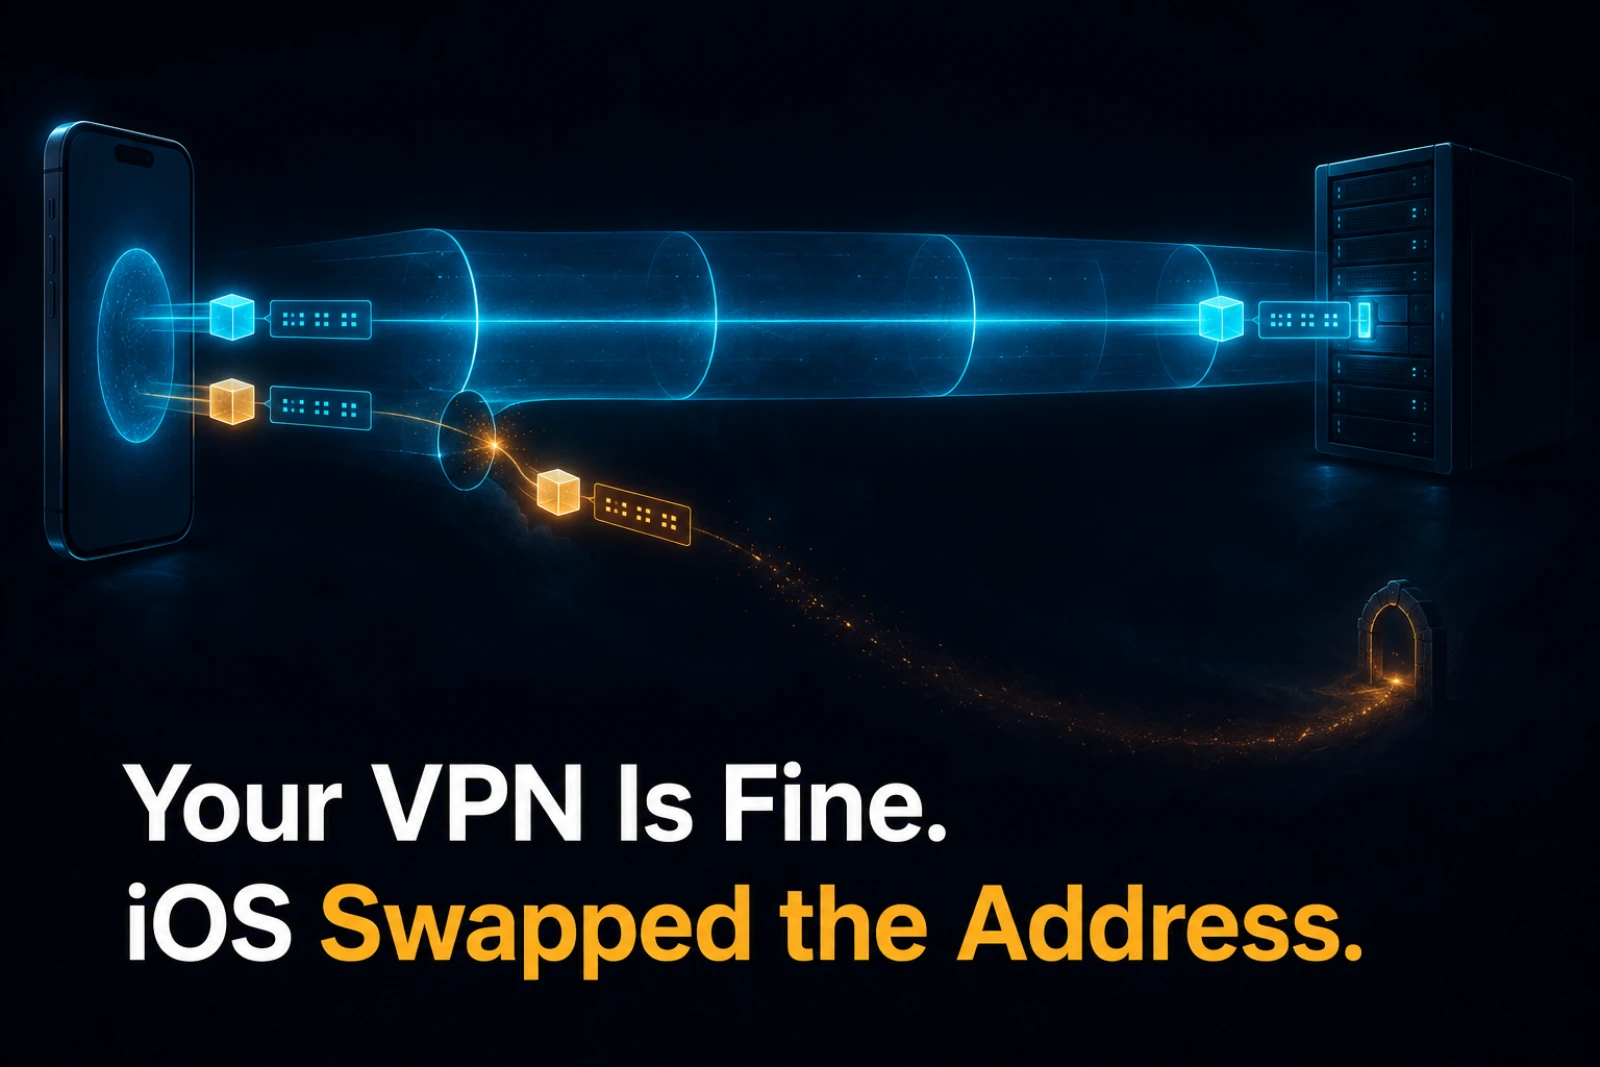
One app, one host, one cellular connection. The HTTP calls reach the server and the streaming connection times out with no error anywhere. Nothing is misconfigured. On an IPv6-only cellular network, getaddrinfo() on an IPv4 VPN literal returns a synthesized NAT64 address that routes straight out of the tunnel, and only the code path that resolves the address itself is affected. This is a field note on recognizing that failure, not discovering it.
2026-08-15
11 min read
Blog
When an agent reports an action it never actually completed, the lie almost never starts in the model. It starts one layer down, in a tool wrapper that returned 200 the moment the request was accepted rather than when the side effect was observed. This is the completion-ownership bug that has broken RPC systems for decades, wearing a tool schema. The fix is to put ownership in the wrapper: verify the effect before the word success ever reaches the model.
2026-08-13
10 min read
Blog
When the monthly LLM bill jumps several times over, the first instinct is that the model got more expensive or usage simply grew. It is almost always something else: a distributed systems failure mode, retry storms, fanout amplification, cache misses, unbounded conversation growth, that happens to be denominated in tokens instead of network calls. Debug the call graph, not the model price.
2026-08-04
9 min read
Blog
The most common production AI agent failure is treating validation as an assertion, a one-shot pass/fail check, instead of a loop that validates, scores, and decides whether to accept, retry, or escalate. Deterministic code can assert. Non-deterministic model output needs a closed loop, or your agent will report success while doing the wrong thing.
2026-07-28
10 min read
Blog
In a rules-first AI system, the deterministic checks get authority. They gate output and overrule the model judge. But a wrong check with authority is worse than no check at all. A first-principles standard for verifying the ruler before you trust it.
2026-07-17
11 min read
Blog
Every part of an AI system has exactly one right home: a rule, a state machine, or a bounded judge. Control belongs to the orchestrator, not to an autonomous loop. A first-principles boundary for deciding which technique owns which part.
2026-07-09
18 min read
Blog
The reliability of a probabilistic system is set by how much of it you let the model decide. A first-principles standard for shrinking the stochastic surface, on the generation side and the evaluation side.
2026-06-24
13 min read
Blog
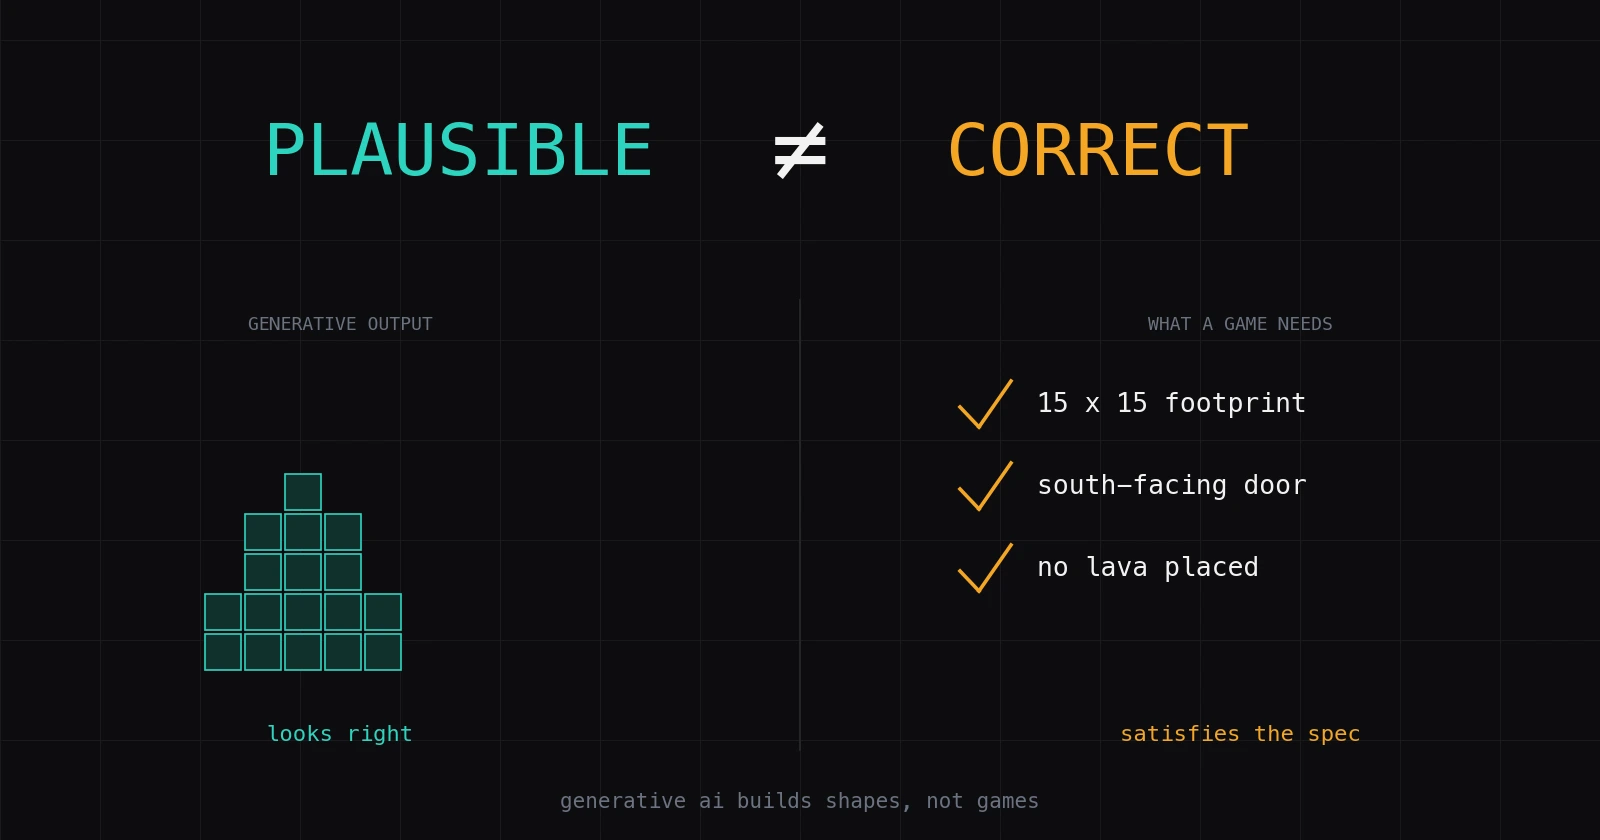
Generative AI nails plausible shapes but misses constraints, composition, and verification. A first-principles read of the gap, and the architecture that closes it.
2026-06-20
12 min read
Blog
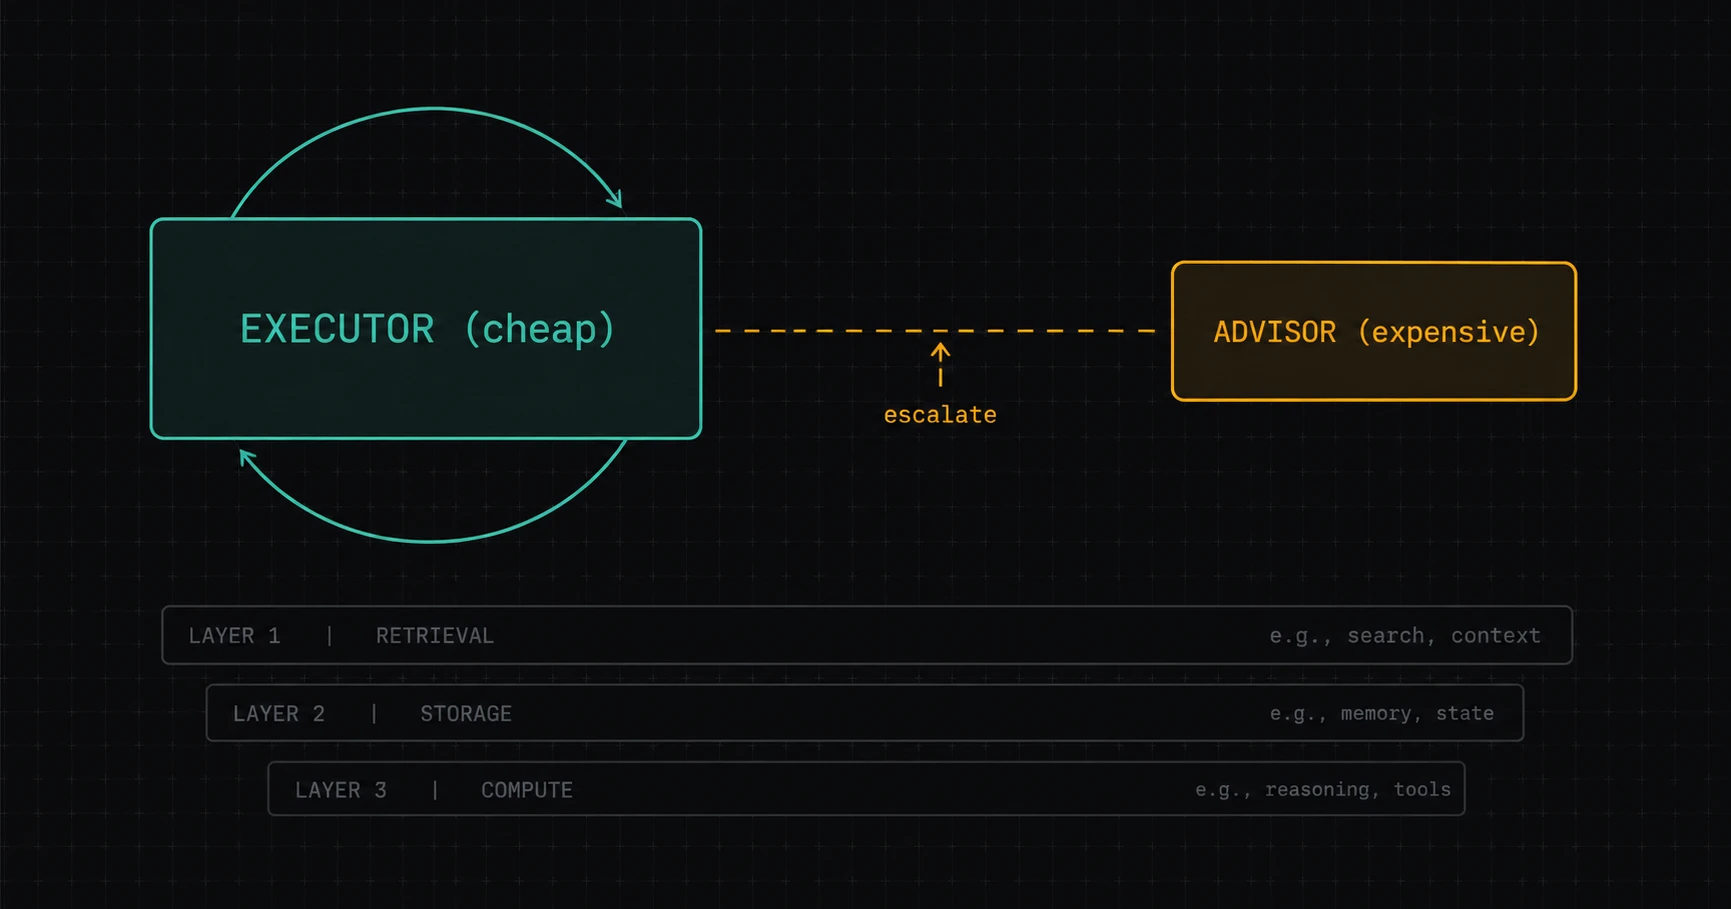
Anthropic named the advisor strategy in April. Tobi Lutke made it viral in May with Qwen plus GPT-5.5. Stanford's HazyResearch formalized the same shape earlier. One cost-curve frame unifies all three: a cheap executor runs the loop, an expensive advisor weighs in only at hard decisions. The third recursion.
2026-06-15
21 min read